Showing posts with label data. Show all posts

Saturday, 24 September 2016

FODMAPs 01 – Data collection

There’s something in my diet that ain’t sitting right. It makes me feel bloated, fatigued and just damn uncomfortable. It’s been like this for years, though it’s been tolerable. Recently I went to a dietitian/nutritionist to learn more about what I should and should not shove down my mouth.

After describing my general diet, I received advice that will sound obvious to most. I need more fruits, vegetables, fibre and water.
“How many fruits and veges am I supposed to eat?”, I asked.
“Two serves of fruit, three serves of vegetables a day.”
“Oh, so the recommendation hasn’t changed since kindergarten?”. I was really hoping that it had been scaled back to two fruits per day. Or one magic fruit pill.

I took the advice as best as I could manage (who has time to eat five serves of vegetables a day? Takes so long to chew). There were marginal improvements. I felt less bloated and fatigued, so my decisions were leading me in the right direction. Similarly, I had stopped drinking coffee back in March and noted improvements. Each dietary change added an improvement.

However, I still feel uncomfortable. Years ago I attempted to rectify my dietary issues with data. I recorded what foods I was eating and what symptoms I felt day to day with the intention to analyse my way to a remedy. I planned to “net” what foods caused upset. I never got around to the analysis.

I’m getting around to it now. I have the right tools.

The nutritionist said I should try a low FODMAP diet. FODMAPs are a group of carbohydrate that are poorly digested. After a FODMAP diet of at least 6 weeks, I’ll gradually reintroduce different FODMAP groups and note my tolerance. I can identify my problem foods then avoid them. But not ice cream. If ice cream is a problem food, I’ll just take lactase beforehand.

I need an app that collects my food intake. I’ve used myfitnesspal in the past. When I Googled for instructions on exporting my data, I couldn’t find a clear guide, or it was a paid option. I can log foods with the Fitbit app, however retrieving the data is also not easy. The Fitbit R scraper I use does not retrieve food data. I would have to access my data via an API.

Instead I’ll use the Memento Database app. Memento Database allows users to customise fields for data capture then easily export the data as CSV. My “Food” library captures the foods or ingredients I consume with the current datetime captured upon entry. I will use short general labels for foods and ingredients as possible since I’d like to group the foods for analysis.

My “Symptoms” library captures a symptom with the datetime. I used to enter detailed symptom descriptions. I want to keep it brief. I'll include feelings of "Fatigue" or feeling "Bloated". The symptoms will be placed in a single-choice list. I expect that these symptoms will decrease as I persist with the lower FODMAP diet. The symptoms will increase when I reintroduce the problem FODMAP groups. Ice cream will totally be fine. Totally.

I will combine this food and symptom data with Fitbit data, namely calories burned, weight and sleep. I’m curious to see if my weight changes with the diet (assuming little change in the calories burned day-to-day) or if my sleep improves. 

In say, 6 weeks’ time, I’ll have data to wrangle then analyse.

Sunday, 7 June 2015

Get the data – JSON APIs

I have recently been moving away from accessing data via CSVs (comma-separated values) to APIs (application programming interface). An API is “a set of programming instructions and standards for accessing a Web-based software application or Web tool” [1]. Why not just download the CSV then suck it into your analytics tool of choice (mine being R)?

I am developing a new reporting system at work (got me a new job). Automation is a priority. I want users to double click an icon to generate the latest report. Full automation will be achieved by automating the separate process that link one form of data to another. Raw data to tidy data is achieved via my custom R programs. Analysed data to report data could be achieved via a web app accessible by users. These data forms and the process that produce each build the “data pipeline”. I’m not sure if I made up that term myself or I read it online and I’m not attributing the source.

What about just getting the data? The first process in the pipeline it to get the data. Traditionally, I would save the CSV file in a directory, write the script to read the data into R, then run the script. With this approach I have to:
  • Visit the location of the data (such as a website)
  • Save the data as CSV into a directory
  • Run the R script.

OMG – visit the location AND save it! So much work. And what if the CSV is like, lots of megabytes? The API approach would be as follows:
  • Download the data directly into R. 

Boom!

However, the setup to download API data took a bit more fiddling-around than I expected.

The survey website API I’m accessing data from permits two flavours – I could download the data as JSON files or XML files. I will not go into detail about how these differ. Look it up yourself. I chose JSON. I actually can’t remember why.

I knew that R had packages to handle JSON files, namely, jsonlite. This is what I needed the package to do:

  • Download the JSON file
  • Convert the JSON file format to a data frame (something that resembles a spreadsheet). 

It took a bit of trial and error to get the download part to work. Eventually the webpage data appeared in R in something that I assumed was JSON format. Here’s a snippet:


I’ll come back to the red box later. The jsonlite package includes a function that converts the JSON format to a data frame. However, after applying it I received an error message indicating a “lexical error”. Something in the JSON format was not in proper JSON format. Unless the data was correctly formatted, I was unable to get my data frame.

Thankfully, I have a colleague who is a JSON guru. His name happens to be Jason. No joke. I’m thinking of changing my name to “R” for consistency. He looked at the format and said it was the “\r\n”. “\r” indicates that there is a new line in the text. The backslash is an “escape character”. The escape character lets R know that the letters “r” and “n” or not actual strings – with the escape characters they become a symbol for a new line.

Jason said I could get past the error by replacing “\r\n” with “\\r\\n”. The double backslash escapes the escape characters. R will read “\\r\\n” as “\r\n\” - a new line. The function gsub finds the old and replaces it with the new

theJSON <- gsub("\r\n", "\\\\r\\\\n", theJSON)

theJSON” is the string of JSON data. What’s with all the extra escape characters “\\\\r\\\\n”? I require one escape character for each escape character I’m inserting in. Since there are two backslashes before the r and n in “\\r\\n”, I’ll need two more for each - "\\\\r\\\\n".

I re-ran the script and got past the error message. Success! Then I ran into another lexical error. Oh no! Upon each error, I updated the substitutions including:

  • theJSON <- gsub("\t", "", theJSON) # Replace tab symbol 
  • theJSON <- gsub("[0-9]*\\\\[0-9]*\\\\[0-9]*", 'DATE', theJSON) # Replace date with string "DATE" 
theJSON <- gsub("\\\\\"", "'", theJSON) # Replace backslashes with single quotation mark

The updated process:
  • Download the JSON file 
  • Convert the downloaded data to correct JSON format 
  • Convert to a data frame. 
Success!


References and notes

Sunday, 28 September 2014

Word clouds using the wordcloud package – R

Everyone loves word clouds. But how do you create them? Thankfully, there is an R package for the purpose, called “wordcloud”.

First, I needed to install the wordcloud and the text mining (tm) packages. The RColorBrewer package is required (if you don’t have it already).


I need a bunch of words. I've always liked the introduction speech that V makes in V for Vendetta [1]. I set the words as a character.


I would like to restrict the word cloud to v-words only. There are a number of steps required to present only v words.


  • The string is split up into separate words as a data frame. Remember, a data frame is "a table, or two-dimensional array-like structure, in which each column contains measurements on one variable, and each row contains one case".
  • Get the row numbers of the data frame containing words that start with v. This is achieved by use of metacharacters ^[Vv] which will search for the start of each word with either an upper or lower case v.
  • Use the row numbers to subset the words from the data frame. That is, the non v words are excluded.
  • Some of these v words end with punctuation marks like full stops and commas. These are removed using the gsub() function and metacharacters [[:punct:]].
  • The remaining text of v words free of punctuation are fed into the wordcloud function with parameters defining the size of the text and colours.

Coolness - I have my v words as a word cloud. However this isn't a particularly exciting word cloud since each word only appears once, thus the text are the same size and colours. Let's try the following quote (spoilers!) from Walter White in Breaking Bad [2].


Looking at the quote we can see that the words "I" and "you" occur a number of times. Let's run some code and produce the wordcloud.


Great, but I cannot see the "I" and "you". Such "stop words" are not included by default when using wordcloud. Also notice that "Skyler"  and "NASDAQ" are lower case. Further, the apostrophe has been removed from "you're". 

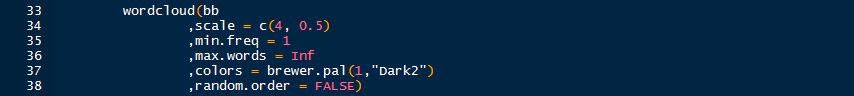
What if I wished to include all words from the quote, adjust the capitals and keep the apostrophes? Starting again with the quote (bb – highlight and run it again), the following code is run [3].


After running the first nine lines, the quote looks like the below. 


The code takes the character string, splits it into separate words, counts the frequency of each word, sorts the matrix, creates a data frame that is fed into the workcloud function to produce the word cloud.


Done! All words are present. One could remove the stopwords from the quote by using the following. 


Then the code above (in the screengrab before the final Breaking Bad word cloud) can be run to generate a new wordcloud free of the common English words. Happy word clouding!


References and notes
1. Click here for a very excellent V for Vendetta kinetic typography of the speech.
2. If you have yet to watch Breaking Bad, DO NOT watch this spoiler.
3. The keen observers will have noticed bb <- stripWhitespace(bb) as the first line. This command takes the character quote and removed any spaces (such as those created by using tab). This line is required, otherwise the frequency table will tally these white spaces and distort the wordcloud.